10 Suspects Why Data Science Projects Fail
Most data science projects never deliver value, and the reason is rarely technology. From underestimated data engineering to the law of the instrument and fear-driven data silos: 10 common traps and how to avoid every single one.
Who should read it?
Managers, team leads, and anyone who funds or works with data teams
Intro
60% - 80% of Big Data projects fail. The number comes from industry surveys, and it has barely moved in a decade, which is the part that should worry you. A decade of better tools, cheaper cloud storage, and smarter algorithms has not fixed it.
That is because the technology was never the bottleneck.
The ten traps below come from Hebing and Manhembue's "Data Science Management," a book written by two people who have run these projects inside real companies. Some of the traps are technical, but most are not. The most dangerous ones are about people. We take also the perspective from psychology and sociology to explain them better.
Trap 1: Underestimating data engineering
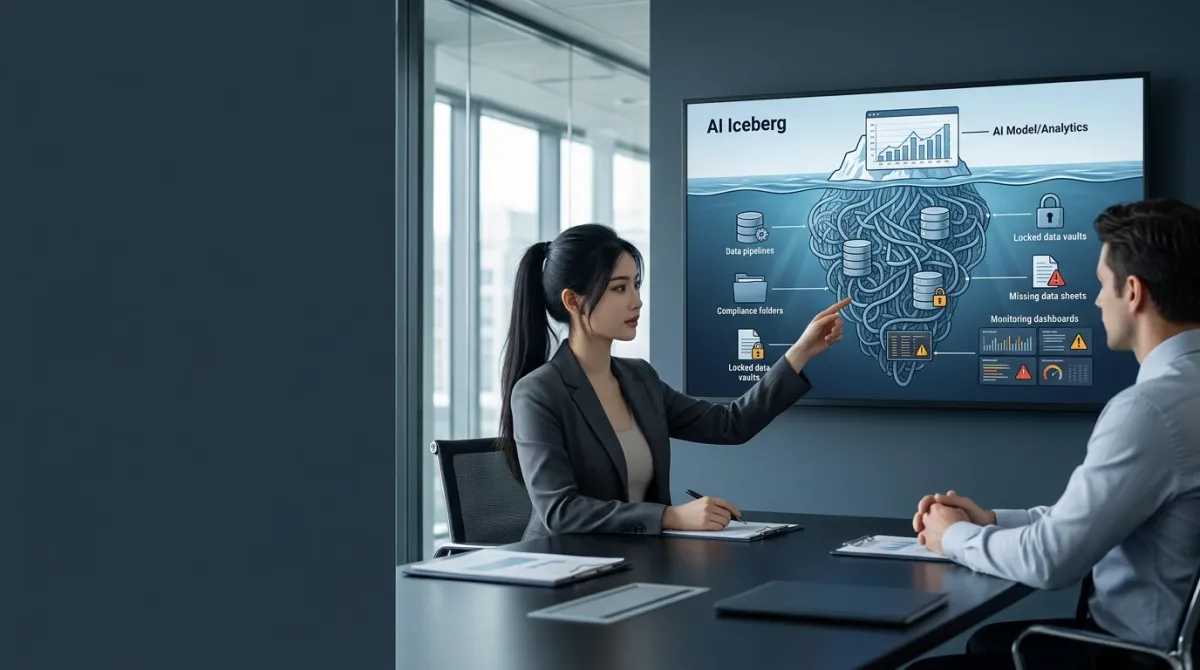
Ask a manager how long it takes to build an AI feature and you will hear a number based on the demo, not the data. The actual work of getting data clean, connected, and usable takes most of the project time, and it is systematically underestimated by managers.
The reasons are mundane. Data quality is worse than anyone admits. Security and compliance requirements add friction nobody budgeted for. The toolset keeps changing under your feet.
A 2020 O'Reilly survey asked organizations about their data quality problems and got a depressing list: badly labeled data, unlabeled data, too many inconsistent sources, missing metadata, bias in the data, and, notably, too few people who even work on data quality. The authors of the book suspect the real situation is worse than the surveys show, because some organizations do not realize data quality is a thing they should be measuring.
Why does this matters beyond engineering?
A model trained on bad data is not a technical problem, but a trust problem. To you it is still a confident machine for producing decisions, but in a hospital or a bank it turns into a governance problem or a legal problem giving wrong data. Garbage in, garbage out.
Trap 2: Data silos, and the fear that keeps them locked
A data silo is a database in one department that another department cannot reach. SAP here, Oracle there, a Snowflake warehouse somewhere else. The fix is known: data integrators, pipelines, common standards.
What keeps them locked?
The real silo is sociological. People sit on their data because data feels like power. In many organizations, the department that owns the customer table owns influence over every decision that touches the customer. Sharing the data means giving up that position, and it means exposing your work to constant inspection.
That last part deserves more attention than it usually gets. Once a department's data is visible, the people responsible for it are audited, questioned, and criticized continuously. Publishing data quality issues is dangerous when the company has no way to handle transparency. So people protect themselves and the silo stays.
The lesson is not "break down silos" (a slogan that has never worked once). It is that transparency without psychological safety produces silence. If you want data to flow, first make it safe to show imperfect data.
Trap 3: Picking the model you already know
Data scientists, like every professional, reach for what they are familiar with. If your expertise is deep learning, every problem starts to look like a neural network problem. This bias toward the known is invisible from the inside, which is what makes it a trap.
The discipline that helps is boring: write down two or three candidate approaches before choosing, including the simple one, and state what evidence would change your mind.
Trap 4: Overly complex models for simple problems
The dirty secret of applied data science is how often a simple linear regression would do the job. Complex models are more accurate, up to a point, but that accuracy buys you opacity, compute cost, and fragility. A model nobody can explain is a model nobody can challenge, which becomes an organizational liability the first time a regulator, a customer, or your own CFO asks "why."
There is a real tradeoff curve here: rule-based systems and linear models sit at the interpretable end; random forests, support vector machines, and neural networks climb toward accuracy while sliding toward black-box territory. The right choice is the least complex model that meets the actual requirement. Anything more is a cost you chose not to notice.
Trap 5: The curse of dimensionality
Each feature you add to a model is a dimension, and dimensions multiply the amount of data you need. Bellman named this the "curse of dimensionality" in the 1950s, and Hughes showed something that looks paradoxical: model performance first rises as you add features, then peaks, then falls even though you are adding information. The extra columns you just added start to give noise, not signal.
The practical symptom shows up in project plans: compute costs explode, training runs drag, deadlines slip. The cure is ruthless feature selection, which is unglamorous work that produces no demo. That is exactly why it gets skipped.
Trap 6: Smoothing away the outliers (to please the room)
Here is a trap with a psychological engine. Domain experts have expectations based on experience. The data sometimes disagrees with them. A data scientist under pressure can respond by adjusting parameters or quietly ignoring outliers until the model's output matches what the experts expected all along.
Everyone in the room feels better. The experts were not challenged, the data scientist got positive feedback, and the project stayed on schedule.
The cost is invisible but real: outliers are often the most informative points in a dataset. They are the fraud cases, the anomalous sensor readings, the customers who behave in ways your business model has not imagined. A model tuned to meet expectations is no longer measuring reality; it is flattering it. The project may fail a year later, for reasons nobody will trace back to this moment.
Sociology has a name for the general pattern: it is the same conformity pressure Asch documented in the 1950s, when people gave obviously wrong answers to match a group. The boardroom version is quieter and wears better clothes.
Trap 7: The law of the instrument
Give a child a hammer and everything looks like a nail. Give an organization a data science team and every problem starts to look like a machine learning problem.
The book includes a memorable comparison of how leaders imagine AI versus what building AI actually involves. The imagined version: data goes in, value comes out. The real version: data selection, collection, integration, storage, cleaning, transformation, feature engineering, model selection, training, evaluation, tuning, registration, deployment, monitoring, retraining, plus legal, ethical, security, and acceptance hurdles at every step.
Applying AI to a problem that a regression would solve is not ambition. It is cost multiplication with extra failure modes. The corrective question is simple and worth asking in every kickoff: "What is the simplest method that could plausibly work here, and why is it not enough?"
Trap 8: Too much, too early
Companies think in fiscal years. Data science dividends rarely arrive on a fiscal-year schedule. The mismatch alone creates the trap: stakeholders expect savings, better processes, or a new revenue model within the same budget period, get frustrated when results take longer, and cut support for future projects.
The deeper issue is that data science is closer to research than to construction. Research fails on the way to working, by design. If your governance treats every failed experiment as wasted money, you have built a system that guarantees either dishonest reporting or no experiments. Neither survives contact with reality.
The business parallel is the classic innovation-funnel problem: portfolio thinking with many small bets beats one large bet that must succeed, for the same reason venture capital works the way it does.
Trap 9: Unclear goals, spoken in two languages
Decision makers and data scientists usually speak different languages. One side says "product" and means the end customer; the other hears "backend" and means the software. Even the term "artificial intelligence" refers to completely different objects in each group's head. Projects drift because the goal was never one goal.
The book's fix is a return to an old tool: SMART goals, as introduced by George Doran and used heavily by Peter Drucker. Specific, measurable, attractive, realistic, terminated. "We want to get better" is not a goal. "Increase revenue in the women's sneaker department by 20% within two years" is.
The benefit of a specific goal is not measurement, it allows disagreement to surface early when it is cheap.
Trap 10: A project is not a product
Projects end. Software does not. Most data science initiatives produce a working demonstration for the final presentation, and everybody implicitly understands the deliverable differently: the data scientists assumed the demo proves the concept, the stakeholders assumed the system now runs forever.
Nobody says this out loud, which is why it surfaces late, in conflict, when expectations collide. A production system needs monitoring, retraining, maintenance, and an owner. If that was never planned, the project did not fail technically. It was mis-sold from day one.
What is behind it?
A culture that hides failed experiments. They are not one-off project pitfalls; they are conditions of the whole organization. If your projects keep dying quietly even with clear goals and demos, then now you know where you need to improve.
Key Takeaways
The 60-85% figure is not destiny. It is a measurement of how organizations behave, and behavior can change.
- Count how many of these traps are currently active in your organization.
- Fix the cheapest one first. It is usually "unclear goals" rather than "data quality".
- Take the list as a checklist for every new project kickoff