Papers, Please: Documenting the AI Lifecycle for EU AI Act Compliance
The EU AI Act does not ask whether your model works. It asks whether you can prove how it was built, what went into it, and who is responsible now. The documentation an AI provider needs across the whole lifecycle.
Who should read it?
AI providers and teams shipping general purpose AI models, compliance leads, engineering managers who own the paper trail.
Sibling article
- Offline Is Not Enough: What It Really Takes to Make a Local Model GDPR Compliant
Papers, Please
The customs officer in the game "Papers, Please" does not care that your documents are good. He cares that they exist, that they are current, and that they match. The EU AI Act is that officer for artificial intelligence, and the inspection covers the entire life of a model: what data trained it, which decisions shaped it, how it was secured, why it made a particular call, and what risks it carries right now, not at launch.
The Act's heaviest documentation duties fall on providers of General Purpose AI (GPAI) models, the large systems like Qwen, DeepSeek, or the frontier models that can be adapted to almost any task (high-risk systems under Annex III carry a parallel documentation load, but that is a separate article's subject). For GPAI, the law demands a record of the entire lifecycle, including training, design, and risk mitigation. The logic is simple: you cannot show compliance after the fact for something that was never recorded as it happened. A model shipped without a paper trail is a model whose history nobody can reconstruct, and reconstruction is exactly what a regulator will ask for.
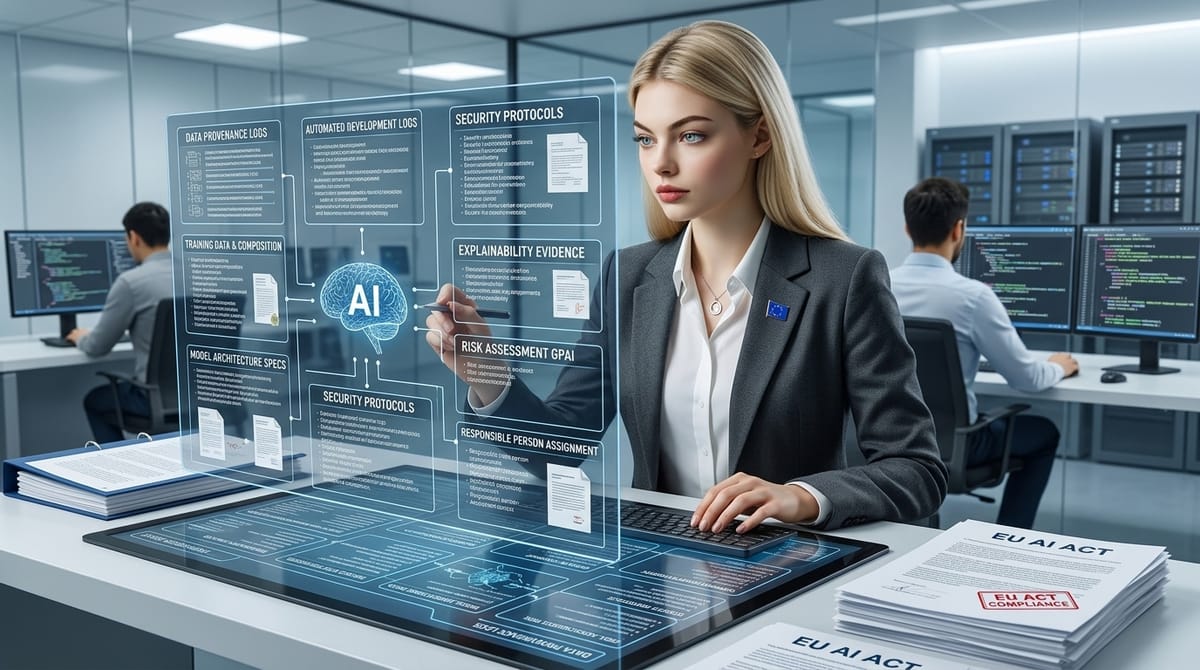
The practical question is: "What to put in the file?". The answer splits into 5 blocks that follow the lifecycle:
- data and design before training
- documentation during development
- security
- transparency
- systemic risk.
Block 1: Data and design, before training
Compliance starts before a single GPU is switched on, because the paper trail has to prove the model was built legally and ethically.
Training data. You must document where your training data came from and show compliance with copyright law. That means recording the sources, the licenses or legal bases attached to them, and the checks you ran. If you build on open-source models, the provenance work gets harder, not easier: for Chinese models like Qwen or DeepSeek, you must verify and record their data handling policies yourself. An open license on the weights says nothing about the data used to train them. The verification and the record of that verification are yours to produce.
Design decisions. Keep a record of why a specific architecture, say a Transformer or a Mixture-of-Experts setup, was chosen, and how it was configured. This sounds bureaucratic until you remember who needs it: the person auditing your model two years from now needs to distinguish a deliberate engineering choice from an accident nobody noticed. Architecture decision records, the short documents engineers already use to capture context, options considered, and the reason for a choice, slot directly into this requirement.
Risk assessment. Before deployment, document a risk analysis following the NIST AI Risk Management Framework, a voluntary standard the Act does not mandate but which gives the analysis a usable shape. The analysis must identify technical risks (the model fails under distribution shift), ethical risks (biased outputs), and social risks (misuse at scale). The structure matters because it turns "we thought about risks" into named risks, named mitigations, and named owners.
Block 2: Automating the documentation during development
Manual documentation fails in AI development for the same reason manual testing fails: the pace outruns it. If the record depends on someone writing notes after the sprint, the record will have gaps exactly where the interesting decisions happened. The fix is to let the tooling write the audit trail while the work happens.
Context files with Crush and Claude Code. The terminal-based coding agent Crush reads CRUSH.md files from the project root: the project's conventions, build commands, and rules, written once and combined into the agent's context. Claude Code does the same with CLAUDE.md. These files are not generated logs, but they are documentation with a regulatory use: when a regulator asks how AI-assisted development was governed, the written instructions, the guardrails, and the conventions the agent worked under are sitting in the repository. The running record itself comes from the agent's session logs plus one discipline, described next.
Context files as project memory. The rules, architectural context, and steering prompts these files carry are exactly what an auditor needs to see.
Version control per AI change. The branch-per-change discipline is what turns agent sessions into an audit trail: one Git branch for every AI-generated change. Each iteration of the model or application is versioned and traceable, and the diff between branches is the answer to "What exactly did the AI change?" before it went anywhere near main.
Together these turn development itself into the documentation process. The alternative, reconstructing history from memory after the fact, is precisely what the Act makes impossible to defend.
Block 3: Security, layered the ENISA way
The Act requires evidence of "appropriate technical and organizational measures." The useful structure here is the ENISA multilayer cybersecurity framework, a reference model rather than a legal requirement, but one that maps cleanly onto what the Act expects you to show. The documentation follows its 3 layers:
- Layer 1, foundations: document the standard IT security you already run, such as zero-trust access controls and vulnerability management. Boring, but it is the foundation everything else sits on.
- Layer 2, AI-specific: record the safeguards against threats that only exist for AI. The two canonical ones are:
- Data poisoning
- an attacker corrupts your training data so the model learns the wrong lessons
- Adversarial attacks
- manipulated inputs make a deployed model misbehave. For each, document what you defend against and how.
- Data poisoning
- Layer 3, sector-specific: if you operate in finance or healthcare, document the audit trails and fail-safe plans those industries demand. The measures are defined by the sector's regulators; the Act expects you to show that you adopted them.
The layering is the point: an auditor can start at the foundation and climb, and your documentation should make that climb possible without interviews.
Block 4: Transparency and explainability
Transparency requirements exist to prevent the black box problem: a model whose decisions cannot be explained to the people they affect. Documenting explainability means producing evidence, not assurances.
XAI outputs as evidence. Run Explainable AI methods like SHAP or LIME inside your pipeline and document their outputs. A SHAP analysis showing which features drove a decision is the artifact that proves you can explain why the model reached it. For a loan denial, that is the difference between "the model scored it low" and "the model scored it low because of these three factors." One caveat belongs in the file itself: SHAP and LIME were built for classifiers with discrete features. Applied to generative language models they transfer only partially, so document which method you used, on what output type, and where you fell back to output auditing instead. An honest limitation note reads better in an audit than an overclaim.
Counterfactual explanations. Record tests in the form "if X changed, would Y change?" A counterfactual test that shows flipping a protected characteristic like gender or race does not flip the outcome demonstrates the model is not leaning on those attributes. Systematically documented counterfactuals are among the cheapest strong evidence you can produce, because the tests are mechanical once the pipeline supports them.
Block 5: Systemic risk for GPAI
The requirements tighten sharply for the most powerful models. GPAI models with systemic risk are presumed to be those trained above 10^25 FLOPS (the Commission can also designate capable models below that line). At that scale, the law treats the model as capable of affecting public health, safety, and fundamental rights, and the documentation reflects it. The other side of this ledger, what GDPR demands of a local deployment running such a model on your own hardware, is the subject of the companion piece "Offline Is Not Enough."
Ongoing assessments. You must perform and document continuous assessments of systemic risks. Note the tense: not an assessment before launch, but ongoing ones, because a model's risk profile changes as it gets deployed in new contexts and as capabilities drift with updates.
Downstream liability. The provision that catches teams by surprise: if you significantly fine-tune a pre-trained GPAI model, you may legally become the provider. The compliance burden, including documenting the training history, transfers to you. Buying a strong open-weight model and adapting it does not outsource the paperwork; it moves the paperwork into your building. Teams that planned to "just fine-tune a foundation model" should budget for that document load before the fine-tuning run, not after the first regulator letter.
The lifecycle, one table
| Lifecycle Stage | Documentation Action | Recommended Tool/Framework |
|---|---|---|
| Data Prep | Record data sources and copyright compliance. | Manual / data lineage tools |
| Development | Record AI-assisted changes: session logs, one branch per change. | Crush / Claude Code (session logs), Git |
| Context | Capture project conventions and instructions to the agent. | Crush (CRUSH.md), Claude Code (CLAUDE.md) |
| Security | Document defenses against poisoning and attacks. | ENISA Framework |
| Inference | Record explanations for model decisions. | SHAP / LIME |
| Risk | Maintain updated risk and mitigation logs. | NIST Framework |
What to do with this
Start the file before the training run. The data provenance and design decision records are cheap to write while the choices are fresh and impossible to reconstruct later. Wire the automated logs in next, because they only help if they covered the whole process. Then keep the risk and explainability records living documents: the Act's phrase "ongoing" is doing real work. The teams that pass inspection will not be the ones with the safest models. They will be the ones whose papers, when asked for, are there.