The Data Lakehouse Promise: One Repository, Fewer Pipelines, New Trade-offs
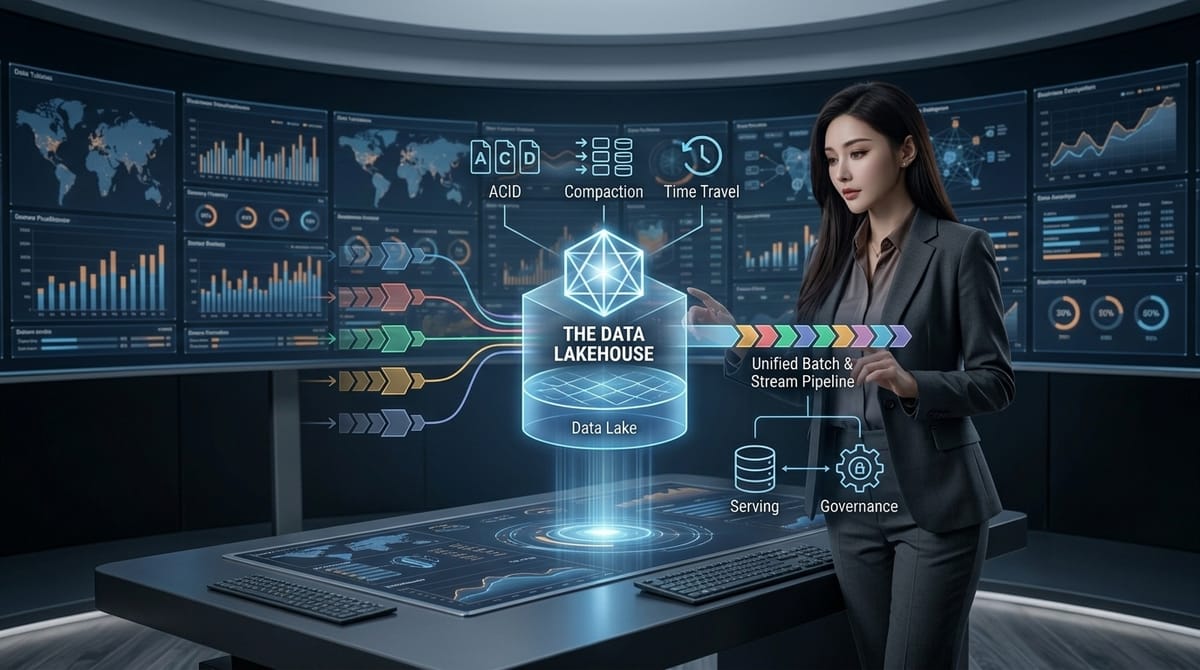
A data lakehouse is lake storage plus a transactional table layer. Delta Lake, Iceberg, and Hudi add ACID per table, time travel, compaction, and one pipeline for batch and stream, but serving and governance do not disappear.
Who should read it?
Data engineers and analytics leads weighing whether the warehouse can be retired
Intro
By 2020 a familiar tension had settled over most data platform teams. Parts 2 and part 3 of this series described it: the data lake (DL) stores everything cheaply but behaves badly when you need reliability, and the relational data warehouse (RDWH) delivers reliability but costs money, locks data into a proprietary engine, and forces you to run a 2nd copy of the data through a 2nd set of pipelines. Two repositories, two pipeline stacks, two governance regimes. The lakehouse is the answer to a question that follows naturally from that history: "What if we could drop the warehouse and keep just one repository?"
The promise is seductive, and the mechanics are genuinely clever. We need to be careful not to sell the lakehouse as a universal endpoint. A lakehouse removes one layer of duplication. It does not remove modeling, serving, governance, or operations.
What a lakehouse is (and what it is not)
Strip away the marketing and a lakehouse is a data lake with a transactional layer on top. All the data still lives in the lake, in files on object storage. What changes is that those files are written and read according to a table format that adds warehouse-grade behavior: transactions, schema enforcement, fast updates.
There are 3 noteworthy implementations: Databricks' Delta Lake, Apache Iceberg, and Apache Hudi. All 3 are transactional table formats or layers, not storage engines. This distinction matters more than most vendor slides admit. Delta Lake does not store your data. Your data sits in Parquet files on your data lake, exactly where it would have sat anyway. What Delta Lake adds is a transaction log alongside those files that records every change made to the table. That log is what turns an ordinary collection of Parquet files into a managed delta table with warehouse-like capabilities. Iceberg and Hudi work on the same principle with different log structures and feature sets.
So the recipe for turning a data lake into a lakehouse is simple in principle: when you write data to the lake, save it in the lakehouse table format instead of raw files. The catch is compatibility. Anything that interacts with those tables, from query engines to BI tools to your own scripts, has to support the format. Ecosystem compatibility, which we return to later, is a real cost.
What the transactional layer buys you
The capabilities that table formats add read like a checklist of warehouse features that raw lakes lack.
DML and updates. A plain data lake is optimized for batch processing and storing large volumes. It is not optimized for real-time updates. Changing a row means reading the entire file, modifying it, and writing the whole file back. A delta table breaks data into smaller files organized in rows and columns, and the transaction log tracks changes so INSERT, UPDATE, and DELETE become practical operations, accelerated by columnar storage and in-memory processing.
ACID transactions. Atomicity, consistency, isolation, durability: the 4 properties that make a transaction either fully commit or fully roll back, never half-finish. Warehouse users take this for granted; lake users historically could not. One caveat: ACID support is per single delta table, not across multiple tables. If your workload depends on transactions spanning several tables, the lakehouse does not give you what a full relational database does.
Time travel. Because the transaction log keeps a history of changes with metadata, you can query a delta table as it existed at a specific point in time, view previous versions, or revert to one. 3 use cases: auditing data, debugging data, and recovering from mistakes. Anyone who has overwritten a table with a broken transformation and had no way back will recognize the value immediately.
Compaction. The small-files problem is the classic data lake disease: thousands of tiny files from streaming writes, each one dragging metadata overhead with it. Table formats run optimized compaction algorithms in the background, merging small files into larger ones. The process can be automatic, scheduled, or triggered manually.
Schema enforcement. You can specify the expected schema for a delta table, and writes that do not conform are rejected, preventing the slow data corruption that schema-on-read lakes invite. Among enforced rules are nullable constraints, data type constraints, and unique constraints.
One pipeline instead of two. This may be the biggest architectural win. In the lambda-style setups of the 2010s (see part 2), teams maintained separate pipelines for batch processing and real-time streaming, often in different technologies, doubling maintenance. A lakehouse table can serve both workloads on the same data. One pipeline, one system to operate, one place where the batch view and the streaming view agree.
The relational serving layer you may still need
Here is where the honest version of the lakehouse story diverges from the pitch.
Delta Lake remains a schema-on-read, file-and-folder system. Schema is applied when data is read. The folder structure provides no context for what the data means, defined relationships between files do not exist, and each file is in its own isolated island. That is fine for a data engineer with a notebook open. It is not fine for a business analyst pointing a dashboard at the platform.
Two gaps show up in practice:
Dashboard latency. When a use case demands millisecond query response times: create an RDWH, copy the data used for dashboards into it, and accept that you now effectively run a modern data warehouse (MDWH) architecture again. Performance features such as z-ordering can alleviate some of the gap, but not eliminate it.
Concurrency. Heavy dashboard workloads hammer a system with many simultaneous queries. File-based storage with a transaction log is not built for that contention pattern in the way a warehouse's serving engine is.
Meaning and relationships. A layer on top of the lakehouse data that ties metadata to the data, presents it in a relational model, and defines relationships so users can join more than one file. The goal is that the end user experiences it like a data warehouse and never needs to know the data actually comes from Delta Lake. This layer can take many forms: SQL views on top of files that a reporting tool calls, a dataset inside the reporting tool itself, an Apache Hive table, or ad-hoc SQL.
Once you add a serving layer with copied dashboard data and defined relationships, you have reintroduced much of the separation the lakehouse promised to remove. For an increasing range of use cases the lakehouse is the best architecture, and as with any architecture there are trade-offs and concerns when you choose to have no RDWH at all.
The data journey does not change
It is worth stating what the lakehouse does not change. Data still moves through the same 5 stages:
- Ingestion
- Storage
- Transformation
- Modeling
- Visualization.
The lakehouse consolidates storage and simplifies the pipeline layer, but transformation still has to be designed, data still has to be modeled, and someone still has to decide what the numbers mean. The lakehouse is a change in the storage and engine layer, not a change in the discipline the earlier articles described. Governance, quality checks, and semantic clarity all remain your job.
Trade-offs in operations, skills, and ecosystem
Now let's look at the surrounding system, not the core mechanics.
Ecosystem compatibility. Every tool that touches the tables must support the chosen format. Picking Delta, Iceberg, or Hudi is partly a bet on which format your query engines, ingestion tools, and BI layer support well. The formats are converging and many engines now read several, but gaps remain, and teams should check their actual toolchain before committing.
Skills. Table formats bring concepts (transaction logs, compaction jobs, snapshot management, partition evolution) that a pure object-storage team never dealt with. Someone has to own those operations.
Governance. One repository simplifies some governance questions, but metadata, lineage, and access control still need a home, and the file-folder substrate gives you none of it natively.
Key takeaway
A lakehouse is lake storage plus a transactional table layer, and the layer delivers real data warehouse capabilities: ACID per table, time travel, compaction, schema enforcement, and a single pipeline for batch and streaming. That is a genuine simplification of architecture, and it explains why the pattern spread so fast after 2020.
The lakehouse removes one repository, not one discipline. Millisecond dashboards, cross-table transactions, and high concurrency can still pull you back toward a warehouse-style serving layer, at which point you are running something close to an MDWH with a lakehouse underneath.
Model the data, design the serving layer, govern the platform: the lakehouse changes where the work happens, not whether it happens. In the fifth article, we turn to the data mesh, which attacks a different problem entirely: not where data lives, but who owns it.
Next
Data Mesh Is an Operating Model, Not a Tool You Can Install
Series
- Your Data Architecture Is a Business Decision, Not a Shopping List
- Data Warehouse, Data Lake, or Both? The Architecture Timeline That Makes It Clear
- Data Fabric Is Not Magic: What It Adds to a Modern Data Warehouse
- The Data Lakehouse Promise: One Repository, Fewer Pipelines, New Trade-offs
- Data Mesh Is an Operating Model, Not a Tool You Can Install
- Data Architecture Decision Matrix: Choose the Smallest System That Can Work