Your Data Architecture Is a Business Decision, Not a Shopping List
Why a data architecture is a blueprint shaped by use cases and constraints, not a list of fashionable products. Covers OLTP vs OLAP, schema-on-write vs schema-on-read, the 5 common elements, and the architecture design session.
Who should read it?
Data and analytics leaders, architects, engineers, product owners, and technically curious business readers who need to choose an architecture without being trapped by vendor language
Intro
A retailer decides it needs "a data lake". Budget is approved, a platform is picked, 6 months later the engineering team is loading files nobody can find, the CFO still gets the monthly numbers from a spreadsheet, and the compliance officer is asking where exactly the customer data lives. Nothing about that outcome was caused by the wrong product. It was caused by treating architecture as a purchase instead of a decision.
Architectures all have a place in a certain use case, no architecture applies to every situation, and everything has trade-offs. If you accept those 3 statements, the rest of the series falls into place. If you skip them, every tool comparison you read will feel like a solution looking for your problem.
This article builds the vocabulary you need before the later parts walk through warehouses, lakes, fabrics, lakehouses, and meshes. The goal is not to make you an architect in 10 minutes. It is to make sure that when you sit down with vendors or platform teams, you can state your requirements first and let the architecture follow from them, rather than the other way around.
The concrete problem: buying capability you cannot operate
Consider 3 companies that all say "we need better data". A hospital needs its patient administration system to stay correct to the second, with strict schemas and auditable transactions. A marketing team wants to pull social media feeds, clickstreams, and email data into one place and figure out later what is worth analyzing. A mid-sized manufacturer needs yesterday's production numbers on a dashboard by 8h00, plus a data science sandbox for quality prediction.
These are 3 different architectural problems hiding behind one phrase. The hospital's problem is reliability and control. The marketing team's problem is flexibility in the face of unknown formats. The manufacturer's problem is predictable serving with a controlled expansion path. A single platform recommendation cannot serve all 3 without being stretched in ways that create cost and risk.
To be clear: without investing time up front in designing the right architecture, users will not get value from the data solution.
Planning is not overhead. It is the part that determines whether the investment pays off at all.
The architecture idea in plain English
A data architecture is a high-level blueprint. It defines the overall design and organization of data for a solution: which technologies to use, and how data flows from where it is produced to where it is consumed. The word "high-level" matters. An architecture is not a wiring diagram, not a list of table names, and not a procurement document. It is the set of decisions that make the wiring diagram and the procurement document defensible.
Think of it the way you would think about building a house. The blueprint decides where load-bearing walls go, where water enters, and how people move through rooms. You can still choose fixtures later. But if the load-bearing walls are in the wrong place, no amount of nice tiling fixes the structure. In data terms, the load-bearing decisions are the ones this article covers: what kind of workload you are serving, how strictly data is structured, and which parts of the flow you are building.
Two distinctions carry most of the weight. Let's take them in order.
1st Distinction: OLTP vs. OLAP
The first question your architecture must answer: "Is this system running the business or analyzing the business?"
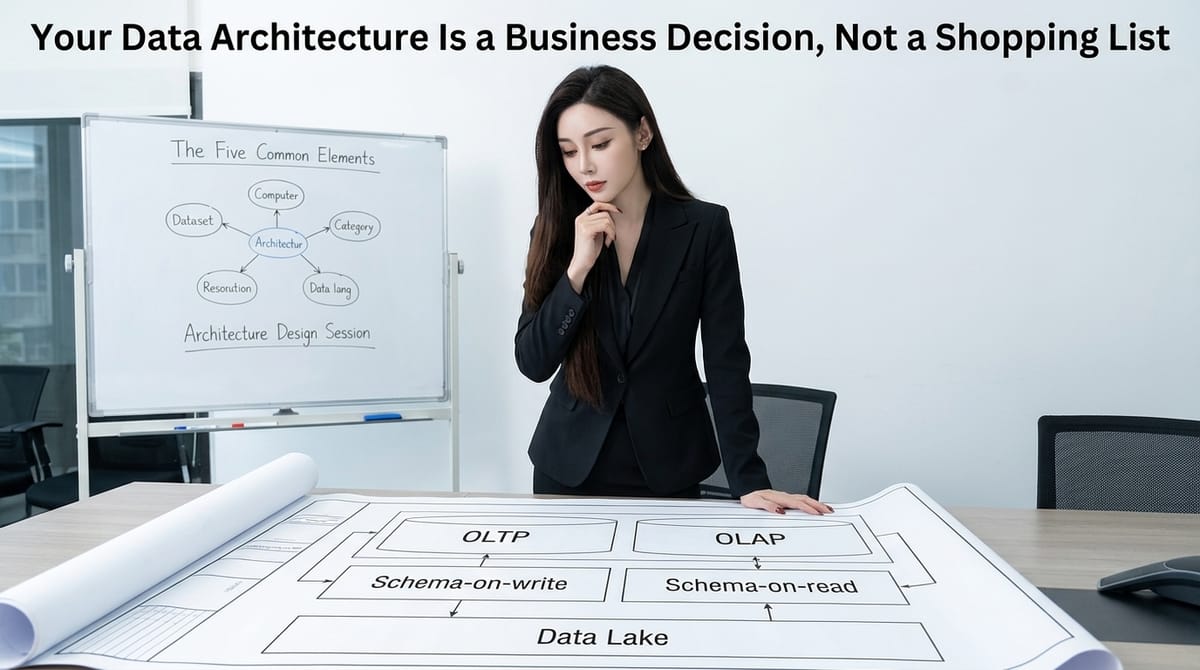
OLTP stands for online transaction processing. This is the domain of relational databases from the 1970s onward, and it is still where most operational systems live. OLTP systems handle many short, fast operations: an order placed, an account debited, a patient record updated. They use a schema-on-write approach, meaning the structure of the data is defined and enforced before anything is stored, which guarantees consistency. Their primary purpose is keeping the business running.
OLAP stands for online analytical processing. This is the domain of relational data warehouses from the 1980s onward. Instead of many small writes, OLAP systems handle complex queries over large volumes of historical data: revenue by region per quarter, churn patterns by segment, production yield by line and shift. Warehouses earned their place by integrating data from many sources into a single version of truth, optimized for analytics rather than transactions.
"Why does the distinction matter architecturally?" Because the 2 workloads punish the same system in opposite ways. Long analytical queries on the database that processes your transactions can slow or block those transactions. Transactional schemas, normalized for fast updates, are too complex for the wide shapes analysts need. This is why the separation of operational and analytical systems is one of the oldest and most durable ideas in the field, and why "just query production directly" is usually the first architecture mistake a team makes.
Ask yourself: "Who touches the data?", "How often?", and "With what tolerance for slowness/latency?" If the answer includes the system where your revenue depends on, the analytical layer needs its own home.
2nd Distinction: schema-on-write vs. schema-on-read
The second question is: "When does structure get applied?"
With schema-on-write, the schema (the formal structure: tables, attributes, data types, constraints) is defined and enforced when data is written or ingested. The schema acts as a blueprint for storing and managing data and for ensuring consistency and integrity. Nothing enters the system that does not conform. The cost is upfront work and rigidity: every source must be modeled before it can be loaded, and changing the model means changing the pipeline.
With schema-on-read, data is ingested without conforming to a strict schema. Structure is defined only when the data is queried or consumed. This is the approach associated with data lakes from the 2010s: raw data of any shape, structured or not, lands in cheap object storage, and meaning is applied at analysis time. The benefit is flexibility in storing data; you can keep everything now and decide later what matters.
Neither approach is smarter. They price the same thing differently. Schema-on-write pays BEFORE you know whether the data is valuable; schema-on-read pays AFTER, in the form of work every analyst has to do to make raw data usable, and in the governance question of what exactly is sitting in the lake. The trade-off between control and flexibility is the single most consequential dial in data architecture, and part 2 of this series traces how it shaped the warehouse, the lake, and everything after. The key point: your choice should follow from your use case. Unknown value and unknown formats push toward schema-on-read. Known questions, compliance pressure, and many consumers push toward schema-on-write. Most real organizations end up with both, used deliberately.
How data moves: the five common elements
Whatever the architecture is called, data solutions tend to share 5 common elements, and walking through them is the fastest way to see where your requirements actually bite.
Sources
"Where does data originate?" Operational databases, SaaS applications, sensors, files, 3rd-party feeds. Count them and note their formats and their owners. A handful of clean relational sources and a flood of messy event data are different architectural problems.
Ingestion
"How does data get from the sources into your platform?" Batch loads on a schedule, streaming pipelines, or API-based integration. Latency requirements decide a lot here. If a number on a dashboard may be a day old, you have options; if a fraud check must see the transaction in seconds, you have fewer.
Storage
"Where does data rest?" Relational tables, a data warehouse, object storage in a lake, or some combination. Cost, volume growth, and the schema-on-write versus schema-on-read decision all land here.
Processing
"What happens to data along the way?" Cleaning, transformation, aggregation, modeling. This is where quality gets built in or patched on, and it is where much of the engineering effort in any platform lives.
Consumption
"Who uses the data, and how?" BI dashboards, ad hoc SQL, data science notebooks, applications, exported reports. Consumption is where value appears, and it is the element teams most often design last and improvise most.
Sketch your data moving through those 5 elements by hand, on paper, before opening any vendor's slide deck. If a source has no clear path to a consumer, you have found a question you cannot answer yet. That is progress; it is much cheaper to discover it on paper.
What this makes harder, and the people in it
A blueprint that ignores the organization operating it will fail quietly. 3 failure modes are common:
- Scope inflation: the architecture that serves every imagined future need serves today's needs badly.
- Skill mismatch: a streaming-heavy architecture with no streaming engineers on the team is a liability wearing a capability badge.
- Governance as an afterthought: schema-on-read flexibility in particular creates a debt that shows up later as "nobody knows what's in there, and legal wants answers now".
The people implications are not a soft add-on; they are part of the architecture. Decide explicitly who owns each source, who can approve new consumers, and what the quality bar is for each use case. An architecture nobody can operate is not a successful architecture, whatever the benchmark results say.
The architecture design session: a practical alignment method
All of this can sound abstract, so here a concrete method for turning it into decisions: the architecture design session (ADS).
An ADS is a structured discussion with stakeholders, both business and technical, focused on defining and planning the high-level design. It is deliberately framed as "think big, start small": use the session to sketch the target blueprint and then identify a small first step that delivers a quick win. The facilitator's job is to learn from stakeholders: their pain points, their goals, and how they imagine the data serving them.
Just as important is what an ADS is not. It is not a technical workshop, not a training, not a product demonstration, and not a low-level requirements session. The moment it becomes a vendor demo, the shopping-list reflex has won again.
The typical shape: set aside at least a day of preparation (venue or video setup, whiteboards, and yes, lunch), then run a full-day session, shortened if the technology domain is new to the participants. Watch for overload; ending early is better than exhausting the room. The deliverables are a high-level architecture blueprint that serves as the starting point for the data solution, and a plan of action for follow-on steps: a demonstration, a proof of concept, or a prototype.
What makes the ADS valuable is that it forces the business, technical, and organizational concerns into the same conversation at the same level of detail. When the marketing lead says "we need real-time" and the engineer asks "for which decision, and within how many seconds?", the requirement either sharpens or reveals itself as an assumption. Both outcomes improve the architecture.
A small decision guide: write it down before you shop
Before selecting any tool, write down these 7 answers in one document. If you cannot, you are not ready to choose a platform, and that is fine; most organizations are not, and the ones that pretend to be pay for it.
- Users
- "Who will consume the data, in what role, with what skill set?"
- Decisions
- "Which business decisions should this data support?" Name them.
- Latency
- "How fresh must the data be for each of those decisions?"
- Data types
- "Structured tables, semi-structured events, free text, images, or all of the above?"
- Quality
- "What happens if a number is wrong?"
- "Is this directional insight or a regulatory report?"
- Compliance
- "Which data is personal or sensitive?"
- "Where may it live?"
- "Who may see it?"
- Team capabilities
- "What can your engineers and analysts realistically build and operate?"
The result is an architecture brief, not a product comparison chart. The next article in this series uses it: we walk the timeline from relational databases through data warehouses and data lakes to the modern data warehouse, and see how each emerged as an answer to specific constraints rather than as a fashion. The one after that covers Data Fabric, then the lakehouse, then data mesh. By the end you will be able to place each option against your own seven answers, which is the only test that matters.
Next
Data Warehouse, Data Lake, or Both? The Architecture Timeline That Makes It Clear
Series
- Your Data Architecture Is a Business Decision, Not a Shopping List
- Data Warehouse, Data Lake, or Both? The Architecture Timeline That Makes It Clear
- Data Fabric Is Not Magic: What It Adds to a Modern Data Warehouse
- The Data Lakehouse Promise: One Repository, Fewer Pipelines, New Trade-offs
- Data Mesh Is an Operating Model, Not a Tool You Can Install